Gemini Omni Flash Extends Video to 40 Seconds: Its Preview Model Retires September 30
Google made Gemini Omni Flash generally available on August 27, 2026, adding scene extension to 40 seconds, first-and-last-frame control, and 360p-to-4K resolution. The old preview endpoint shuts down September 30. Here is what changes for ad-makers, and how the model already runs inside Novoads.

Mauricio Valdivia
·Updated ·14 min
The Ten-Second Ceiling Just Became Forty
On August 27, 2026, Google released gemini-omni-1.1-flash, the generally available version of Gemini Omni Flash, and moved three of the limits that had bounded the model since June. A clip can now be continued in 10-second increments up to a cumulative 40 seconds. You can pin the first and last frame of a shot and let the model generate the transition between them. And output resolution became a parameter, running from 360p through 4K. In the same release note, Google put a date on the old model: the gemini-omni-flash-preview endpoint is deprecated on September 30, 2026.
That deadline is the most actionable line on this page. As of this update, on September 1, it is under a month away, and Google's separate deprecations page lists the same shutdown date with gemini-omni-1.1-flash as the recommended replacement. If anything you run calls the preview model ID, that is the work.
Everything else is the interesting part. This piece does three things: it explains what the GA release actually changed, it separates the real capabilities from the ones that sound bigger than they are (4K, for one, is upscaling), and it places all of it next to the ad-making workflow the model already runs inside, because the gap between a longer clip and a converting ad is the whole story.
What the GA Release Changed, and the Deadline It Set
The June preview generated short clips with sound and let you talk to them. The GA release keeps that and adds control. Four things changed, and one of them is a date.
Scene extension: 10 seconds at a time, to a 40-second total
This is the capability that reframes the model. Google's announcement puts it plainly: "You can extend videos in 10-second increments up to a total cumulative length of 40 seconds." That alone would be useful. The part that makes it work is underneath it: "the model can now analyze up to 10 seconds of prior context," which Google describes as a leap from previous models that only referenced the final second.
The difference between one frame of context and ten seconds of it is the difference between a continuation and a cut. A model that only sees the last frame can match a pose. A model that sees the last ten seconds can match a camera move, a lighting drift, a musical phrase, and a gesture that was halfway through.
The API docs describe the same feature from the other side. Extension works by "generating a seamless continuation at the tail end of the clip," and the model "creates an extension that keeps video, motion, characters and audio coherent by using the last 10s of your original video as context."
Three constraints are worth knowing before you build around it, all stated in Google's own limitations section:
- Tail only. "Video extension is limited to appending to the end of a video; prepending or extending the middle of a clip is not supported."
- 10 seconds of uploaded source. "Input videos for editing and extension must be 10 seconds or less when uploading," unless you are extending a video the model itself generated in a multi-turn session.
- No new dialogue on an uploaded talking clip. Google states you cannot extend an uploaded video where someone is talking to add additional dialogue.
That last one matters more for ad-makers than the first two, and we will come back to it.
First and last frame: you now specify both ends of the shot
The second addition is interpolation. Google's guide: Gemini Omni Flash "supports video interpolation, allowing you to generate a video that transitions smoothly between a starting image (first frame) and an ending image (last frame)." You supply two images in the input list, describe the transition, and the model animates from one to the other. The announcement frames the use case as "complex camera orbits, zoom transitions, or seamless looping clips," because "Omni 1.1 generates continuous video between two keyframes."
Note the precise shape of the promise. Google's release notes describe it as generating "a video transitioning between two images using the image_to_video task with up to 2 images." It is two-image interpolation, not a full keyframe timeline. You get both ends, not the middle.
For anyone who has re-rolled the same prompt eleven times waiting for a camera move to land, this is the more valuable of the two headline features. Extension makes clips longer. Interpolation makes them repeatable, because the two things you were relying on luck for, where the shot starts and where it ends, are now inputs.
Resolution control, and the word Google used
The third addition is a resolution parameter in the video config, supporting 360p, 720p (the default), 1080p and 4K. The model page lists output as 3 to 10 seconds at 360p, 720p, 1080p or 4K, 24 fps.
Read the sentence Google appended to that release note: "1080p and 4K outputs are generated using upscaling." The model page uses the same word, describing support for "video extension, resolution upscaling, and advanced interpolation." So 4K here is a finishing step applied to a render, not native 4K synthesis. That is not a knock, upscaling is exactly what most production pipelines do anyway, but it does mean 4K will not recover detail the 720p pass never had. Judge the model at 720p and treat the top tiers as delivery formats.
The genuinely interesting number sits at the bottom of the ladder, not the top. Google says the 360p tier generates "lightweight previews" up to 60% faster and "at a third of the cost compared to Omni 1.1's standard 720p resolution." A draft tier at a third of the price changes how you work, and it changes it in exactly the direction ad testing already pulls.
September 30 is the date that decides your week
Google's release notes: "The existing gemini-omni-flash-preview endpoint will be deprecated on September 30, 2026." The deprecations page carries the same date in its table, with gemini-omni-1.1-flash listed as the recommended replacement.
Here is the practical shape of the migration:
| Preview (retiring) | GA (current) | |
|---|---|---|
| Model ID | gemini-omni-flash-preview | gemini-omni-1.1-flash |
| Status | Deprecated September 30, 2026 | Stable |
| Scene extension | No | Yes, to a 40-second cumulative total |
| First and last frame | No | Yes, two images |
| Resolution control | No | 360p / 720p / 1080p / 4K (top two upscaled) |
| Released | June 30, 2026 | August 27, 2026 |
If you built anything on the preview ID in July or August, the swap is small and the deadline is not negotiable. Do it before you spend a day on the new features.
What Gemini Omni Flash Actually Is
Strip away two launch days of noise and the model still does three things worth understanding before you decide what it means for your ads.
Video and synchronized audio, from one text prompt
The core capability has not changed since June: Gemini Omni Flash "creates video with synchronized audio from text input." That is the sentence that matters. Earlier text-to-video models handed you a silent clip and left the sound design as your problem. Omni Flash writes the picture and the audio in the same pass, from the same instruction. Google describes it as drawing on "Gemini's knowledge such as history, biology and narrative logic to construct compelling videos," which is a fancy way of saying the model knows how the world tends to look and sound, so the two tracks tend to agree.
For an ad-maker, the practical win is one fewer step between a generated scene and a usable asset. A poured drink can fizz. A door can thud. You are not stitching foley onto silence. Extension inherits this: Google's own prompting guidance for extended scenes tells you to describe the audio in the new section, because the music carries across the seam too.
Grounded in Gemini's knowledge, tuned for physics
The second thing Google is selling is coherence. The model is "grounded in Gemini's real-world knowledge, with improved physics understanding for more coherent motion and interaction." In Google's own words, "Omni has an intuitive understanding of forces like gravity, kinetic energy, and fluid dynamics for more realistic movement."
Physics is where cheap video models usually give themselves away. A liquid that smears instead of pours, a product that melts into a hand instead of resting in it, a bottle that drifts a centimeter between frames: those are the tells a viewer's eye catches in the first second, and they are exactly the artifacts a better physics prior is meant to reduce. If you have compared model outputs before, this is the axis that separates a clip you can run from one you quietly delete. Our breakdown of Seedance 2.0 versus Veo for ads walks through why motion quality, not resolution, is the thing to judge.
Extension raises the stakes on this axis rather than lowering them. A physics error in a 6-second clip is a clip you throw away. A physics error at the seam of a 40-second chain is 30 seconds of good work you throw away with it.
Conversational editing, and the ceiling that moved
You do not have to re-roll the whole clip to change one thing. Google added "conversational video editing," which lets you "refine and edit videos using natural language," and you can "combine inputs like images, text and video to maintain control and consistency over your scene." That is a real workflow improvement: iterate by talking to the clip instead of regenerating from zero.
Length was the catch. At the June preview launch, Google's own line was that "Omni offers 10-second video generations currently, with longer durations coming soon." Two months later, "soon" arrived, but not in the shape the sentence implied. A single generation is still 3 to 10 seconds on Google's model page. What changed is that the clip no longer has to end there. The ceiling did not rise, it became a chain.
That distinction is worth holding onto, because it decides what the model is good for. Forty seconds assembled from four continuations is not the same asset as a forty-second take. It is four beats that agree with each other. For an ad, that is often better, and it is exactly how a good editor would have cut it anyway.
The Other Half of the Original Launch: Nano Banana 2 Lite
Gemini Omni Flash did not ship alone in June. The image model next to it is arguably the more quietly disruptive release, because it makes the front of the pipeline nearly disposable, and the GA release gave it a second job.
Four seconds, three cents an image
Nano Banana 2 Lite "delivers text-to-image outputs in 4 seconds" at "$0.034 per 1K image." The Decoder put it plainly: "Text-to-image generation takes four seconds and costs just $0.034 per image at 1K resolution." At three and a half cents, an image is close to a rounding error. You can generate fifty product mockups for the cost of a coffee and throw forty-nine of them away.
That matters for ads because the still is where an angle is born. Before you commit a video budget to an idea, a cheap, fast image tells you whether the composition, the palette, and the product framing even work.
The image-to-video chain Google is pitching
Google is not selling these as two separate toys. It recommends a chain: "Use Nano Banana 2 Lite as a high-speed image generation model, then pass that image as a reference to Gemini Omni Flash to animate it into a high-quality video." Storyboard first, motion second.
The GA release upgrades that chain in a specific way. Before, you handed the video model one image and hoped. Now you can hand it two, the opening frame and the closing frame, and describe the move between them. The cheap image model is no longer just the storyboard, it is the pair of bookends that makes the shot deterministic.
What "Lite" gives up
"Lite" is a speed-and-cost tier, not the flagship. The trade is fidelity and headroom for throughput: it is built for ideation and volume, not for the single hero frame you will blow up on a billboard. That is the right tool for the front of a testing pipeline and the wrong tool for the one asset that has to be perfect. Knowing which job you are doing is most of the skill.
What This Means for People Making Ads
Here is where the release stops being a spec sheet and starts touching a budget. Three shifts matter.
The draft tier is the news, not the ceiling
Google's pricing page bills the GA model by output tokens: $17.50 per 1M video output tokens, "calculated at a rate of 5,792 tokens per second of 720p video. Under standard pricing, this equates to an effective price of approximately $0.10 per second." So the familiar dollar-a-clip number survives the GA transition, with one important asterisk: the rate is defined against 720p, and it is a token bill underneath, not a flat meter.
Now put the 360p tier next to it. If a preview costs a third of 720p, ten angles drafted at 360p cost roughly what three cost before. That is not a rounding-error saving on a small number, it is a change in what you are willing to try. The discipline it rewards is the one good creative teams already run: generate wide and cheap, kill most of it, then spend the expensive seconds only on the survivor. Google's own suggested workflow says the quiet part out loud, describing a draft room where you "generate 3-4 draft variations in 360p, varying one thing at a time and compare them side by side."
But drafts are not ads. Each surviving clip still needs a distinct hook, a script that sells a different benefit, an actor or scene that reads as native to the buyer, 9:16 framing, captions, and a beginning-middle-end that earns the last three seconds. The model call is the cheapest line in the budget. The expensive part, the one that used to cost a week of briefs and hundreds of dollars a clip when you hired it out, is everything wrapped around it. Our guide to what UGC creators actually charge shows how steep that wrapped cost gets when a human does it.
Run the same math the other direction. A finished, ready-to-post clip inside an ad workflow like Novoads costs from about a dollar for a five-second Seedance 2.0 Mini clip to about $8 for an eight-second Seedance 2.5 clip, and about $26 for a full 30-second Seedance 2.5 take. Set that next to the bare cost of the same seconds of raw output and the difference is not markup for markup's sake: it is the script, the actor, the accent, the captions, the format, and the credits accounting that turn a bare generation into an asset you can hand to a media buyer. The lesson repeats every time a model ships cheaper or longer: the floor on raw video keeps dropping, and the work that sits on top of it keeps its value.
Forty seconds is a different edit, not a longer clip
The temptation with extension is to treat it as permission to make long ads. Resist it. Paid social does not reward duration, it rewards the first three seconds, and a forty-second chain that earns its length is rarer than a six-second one that lands.
Where the 40-second ceiling genuinely helps is structure. A UGC ad has beats: hook, problem, product, proof, call to action. Before, each beat was a separate generation that had to be matched in the edit. Now a beat can continue from the one before it with ten seconds of context behind it, which is the difference between assembling shots and directing a sequence.
There is one limit here that lands squarely on the UGC use case, and it is worth reading twice: Google states you cannot extend an uploaded video where someone is talking to add additional dialogue. So the obvious idea, take a talking-head clip and extend the monologue, is explicitly out of scope. Extension is a tool for scenes, not for speeches.
A clip is still not an ad
This is the trap every price drop tempts you into. Cheaper, longer, sharper raw video makes it feel like the hard part is solved, so people generate a gorgeous forty-second scene, post it, and wonder why it does not convert. The scene was never the problem. The hook, the angle, and the trust signal were, and no amount of physics realism or upscaled resolution supplies those.
A converting ad is an argument delivered by someone the viewer believes, in the format the platform rewards, tested enough times to find the version that works. A text-to-video model gives you one ingredient of that. A better one than it was in June, but one. Our comparison of AI video ad platforms covers where each type of tool fits.
Where It Sits Next to the Models Novoads Already Runs
A new frontier video release is not a threat to a model-agnostic workflow. In this case it is not even a new option, because the model is already here.
Omni Flash is already one of the models in the picker
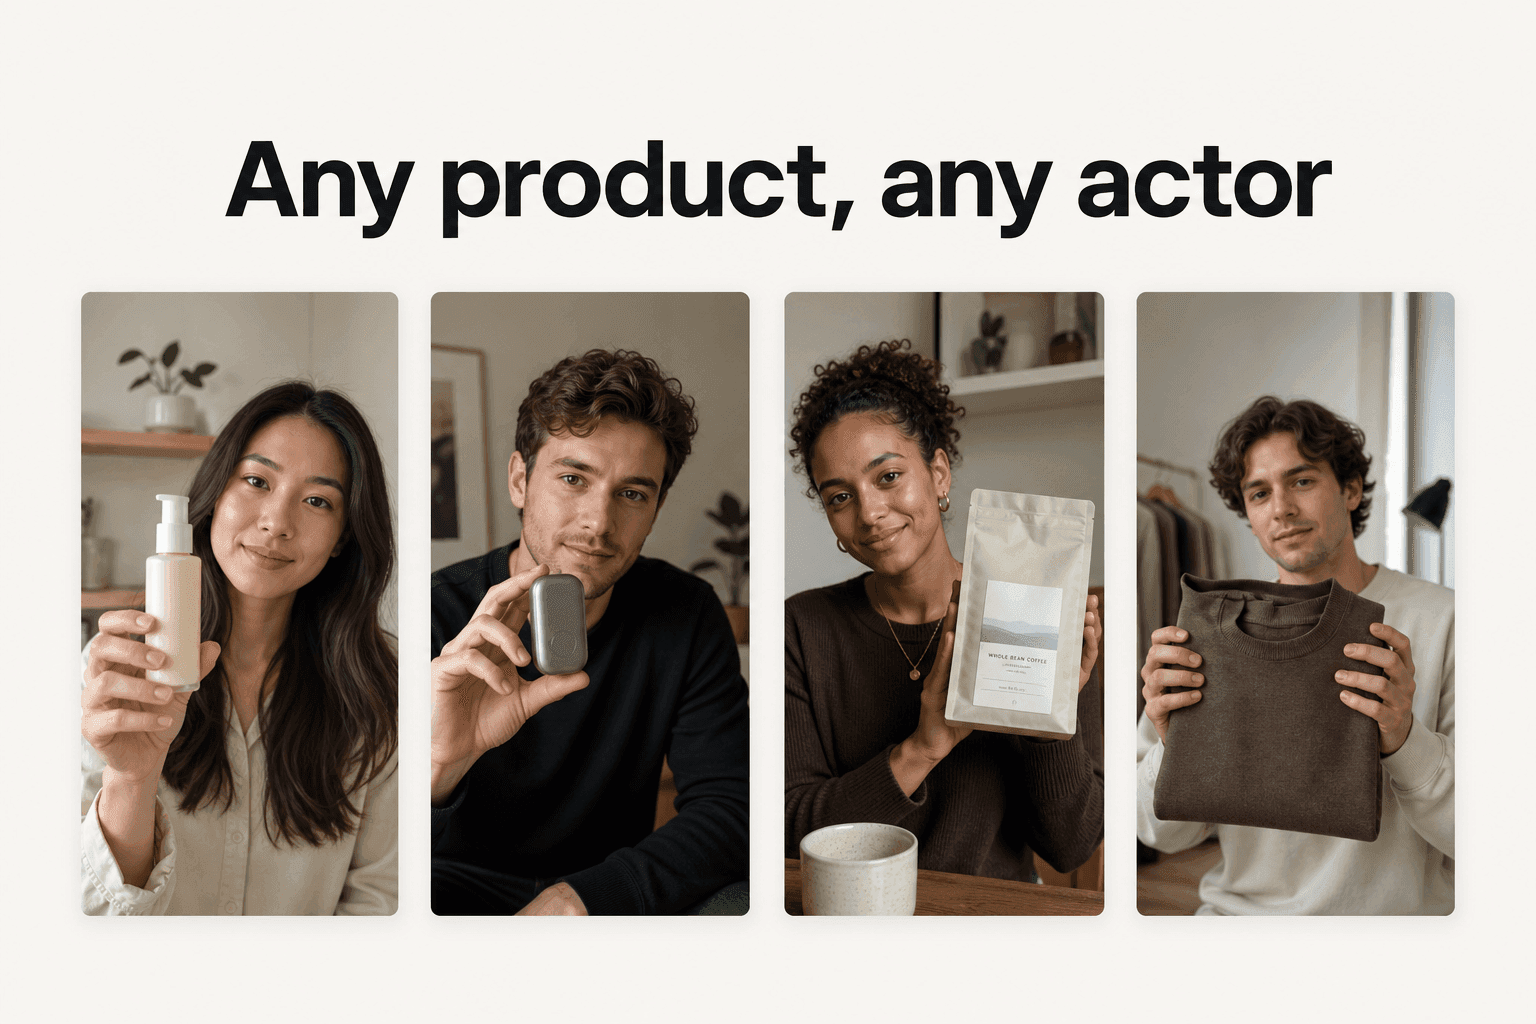
Novoads runs Gemini Omni Flash as one of its video models, next to Seedance 2.5, Seedance 2.0, Seedance 2.0 Mini, Kling v3 Pro and Google Veo 3.1, plus a talking-actor engine for spokesperson clips. So this is not a model to go get. It is one you can pick in the generator today.
Being precise about what our surface exposes matters more than claiming the whole GA feature list. In Novoads, Omni Flash is the 720p generation cell:
- Length: 4, 6, 8 or 10 seconds.
- Aspect: 9:16 or 16:9, defaulting to vertical.
- Inputs: a prompt, up to seven image references, and one video reference.
- Price: 4.2 credits for 8 seconds, 5 credits for 10.
- Not exposed yet: scene extension, first-and-last-frame interpolation, and the 360p-to-4K resolution parameter.
Google shipping a capability into its Developer API is not the same as that capability reaching every surface that serves the model, and saying otherwise would be a promise the generator does not keep.
Model-agnostic beats single-model
The frontier moves every few weeks, and the model that wins your next test is unpredictable. A tool that lets you pick per shot beats one welded to a single engine. Here is how a few of them map to the actual job in an ad:
| Model | Best-fit ad job | Runs in Novoads today |
|---|---|---|
| Gemini Omni Flash | Short scene shots with sound | Yes |
| Google Veo 3.1 | Premium scene and product shots | Yes |
| Seedance 2.5 | Cinematic product motion | Yes |
| Seedance 2.0 Mini | High-volume cheap variations | Yes |
| Kling v3 Pro | Motion-heavy B-roll | Yes |
| Talking actor | A person selling to camera | Yes |
The row that matters most is the last one. Every model above it makes scenes; only the talking-actor job makes the spokesperson, and that is the format most UGC ads are built around. It is also the row Google's own extension limitation quietly points at: a scene model that cannot add dialogue to a talking clip is telling you which half of the problem it solves.
If you want the texture of how these engines differ, our explainers on what Seedance 2.5 does and the open-weights LTX-2.3 model show how fast the frontier is moving, and how similar the headline pitches have become: every new model now promises synchronized audio and better physics.
The part no raw model gives you
A raw API call hands you a clip. It does not hand you an actor library, a script matched to a buyer, lip-sync, a native accent, vertical framing, captions, or the credits accounting to run a hundred variations without babysitting each render. Those are the pieces that stand between a model output and a launched ad, and they are the same pieces whether the underlying clip runs ten seconds or forty.
There is also a compliance layer that the per-second price hides. Both Google models tag their output with SynthID watermarking, and that is not a footnote for advertisers. TikTok, Meta, and other platforms increasingly ask you to disclose AI-generated content, and the label follows the file. A workflow that already thinks about format, captions, and disclosure is doing work the model call does not. The trend line is clear: as generation gets cheaper, longer, and more realistic, the value shifts up the stack, toward the layer that assembles, localizes, and ships the ad responsibly.
How Novoads Turns Model Horsepower Into an Ad
The frontier keeps getting cheaper and longer. What it does not do is assemble itself into something a buyer clicks. That assembly is the product.
Script and actor, not just a prompt
In Novoads, you write or auto-generate a script and pick an AI actor whose age, gender, and accent match your audience, and it produces a UGC-style vertical video with voice, lip-sync, and captions, formatted 9:16 for TikTok, Reels, and Meta. Headline time to a finished clip is about four minutes. You can also upload a product photo and turn it into an ad creative. The model underneath is a swappable component; the workflow is what makes the output an ad instead of a demo.
Native-local, in the buyer's own accent
The differentiator is depth, not model count. Novoads makes native-local video ads in 30-plus languages with regional accents, so a clip sounds like a creator from the buyer's own city rather than a translated script read by a generic voice. A physics-aware scene model does not solve that, and neither does a 40-second chain; the accent and the delivery are a different axis, and it is the one that decides whether a testimonial reads as trustworthy. As platforms tighten disclosure rules for AI-generated ads, that native-local trust signal becomes more valuable, not less.
Volume is the real unlock
The reason to care about a cheaper draft tier at all is testing, and testing means volume. A finished Novoads clip runs from about a dollar for a five-second Seedance 2.0 Mini clip to about $8 for an eight-second Seedance 2.5 clip, and about $26 for a full 30-second Seedance 2.5 take, which is a fraction of a hired shoot and cheap enough to run the many variations paid social actually rewards. You can produce your first AI UGC ad with Novoads on the $49-a-month Starter plan, which grants 50 credits every month, enough for about a dozen videos. Cancel anytime. The point is not one perfect clip. It is never running out of angles to test.
The Model Is the Cheap Part
The GA release is a real step: scenes that continue instead of stopping, shots with both ends specified, a draft tier at a third of the price, and a clear migration date on the endpoint it replaces. Move off gemini-omni-flash-preview before September 30 and the rest of it is upside.
But the release also clarifies something each new capability tends to hide. When the raw clip runs longer, renders sharper, and drafts cheaper, the value has already moved somewhere else: to the script angle, the actor the buyer believes, the accent, the format, and the discipline to test until one version beats the benchmark. Google made the model better at forty seconds. Nobody made the first three easier. The model is the cheap part. The ad is everything you build around it, and that is exactly the part a workflow, not a prompt, is for.
Frequently Asked Questions
What is Gemini Omni 1.1 Flash?
Gemini Omni 1.1 Flash is the generally available version of Google's Gemini Omni Flash video model, released on August 27, 2026 under the stable model ID gemini-omni-1.1-flash. It creates video with synchronized audio from text or images, and the GA release added scene extension, first-and-last-frame interpolation, and a resolution parameter covering 360p, 720p, 1080p and 4K. Google's model page lists output clips of 3 to 10 seconds at 24 fps.
When is gemini-omni-flash-preview being deprecated?
September 30, 2026. Google's Gemini API release notes state that the existing gemini-omni-flash-preview endpoint will be deprecated on that date, and the separate deprecations page lists the same shutdown date with gemini-omni-1.1-flash named as the recommended replacement. Any pipeline still calling the preview model ID needs to move before then.
How long can a Gemini Omni Flash video be now?
A single generation is still short, 3 to 10 seconds on Google's model page. The difference is that you can extend it. Google says you can extend videos in 10-second increments up to a total cumulative length of 40 seconds, with the model reading the last 10 seconds of the clip as context. Extension appends to the end only; prepending or inserting into the middle is not supported, and an uploaded source video must be 10 seconds or less.
Does Gemini Omni Flash generate real 4K video?
Not natively. The GA release added a resolution parameter supporting 360p, 720p (the default), 1080p and 4K, but Google's own release notes say 1080p and 4K outputs are generated using upscaling, and the model page describes the feature as resolution upscaling. Treat 4K as a finishing step on a 720p render, not as native 4K synthesis.
How much does Gemini Omni Flash cost?
Google's pricing page bills the GA model by output tokens at $17.50 per 1M video output tokens, calculated at 5,792 tokens per second of 720p video, which it says equates to an effective price of approximately $0.10 per second. The rate is defined against 720p. Google states separately that a 360p preview costs a third of 720p, which is the number worth planning around if you draft before you finish.
Can I use Gemini Omni Flash inside Novoads?
Yes. Omni Flash is one of the video models in Novoads, alongside Seedance 2.5, Seedance 2.0, Seedance 2.0 Mini, Kling v3 Pro and Google Veo 3.1, plus a talking-actor engine for spokesperson clips. Our surface is the 720p generation cell at 4, 6, 8 or 10 seconds in 9:16 or 16:9, with image and video references. The GA scene extension, first-and-last-frame and resolution controls are not exposed in the picker yet.
Does a cheaper, longer video model replace UGC ads?
No. Forty seconds of extendable scene with sound is a component, not an ad. A UGC ad still needs a hook, a script angle, an actor whose face and accent match the buyer, vertical framing, captions, and enough variations to find the winner. Longer, cheaper raw video lowers one line item; it does not remove the work that turns a clip into something that converts.
Key Takeaways
- Google released gemini-omni-1.1-flash on August 27, 2026 as the generally available version of Gemini Omni Flash, and the release notes set a hard date on the old one: the gemini-omni-flash-preview endpoint is deprecated on September 30, 2026. If your pipeline calls the preview ID, that migration is the most urgent thing on this page.
- Scene extension is the headline. A clip can be continued in 10-second increments up to a cumulative 40 seconds, and the model reads the last 10 seconds as context instead of only the final frame. Extension only appends to the tail, and an uploaded source clip must be 10 seconds or shorter.
- You can now pin both ends of a shot. Supplying a first image and a last image makes the model generate the transition between them, which is the control that turns a lucky render into a repeatable camera move.
- Resolution became a parameter (360p, 720p by default, 1080p, 4K), but Google's own docs label 1080p and 4K as upscaled, not natively synthesized. The interesting number is at the other end: Google says a 360p preview costs a third of 720p, which makes drafting cheap and finishing the expensive step.
- Novoads already runs Gemini Omni Flash as one of its video models, so this is a model you can use here today rather than a tool to go get. Our surface is the 720p generation cell at 4, 6, 8 or 10 seconds with image and video references; the GA extension, keyframe and resolution controls are not exposed in the picker yet.
Sources
- •Google: Gemini API release notes (August 27, 2026)
- •Google: Gemini API deprecations
- •Google: Gemini Omni 1.1 Flash lets you build with more control
- •Google: Gemini Omni Flash model page
- •Google: Generate video with Gemini Omni Flash
- •Google: Gemini API pricing
- •Google: Start building with Nano Banana 2 Lite and Gemini Omni Flash
- •Google DeepMind: Gemini Omni
- •fal: Gemini Omni Flash